How to automate keyword research without losing intent
Pasting hundreds of search terms into a spreadsheet kills your momentum. When you automate keyword research, you replace manual data entry with a system that pulls search volume, categorizes intent, and clusters queries in minutes. According to industry benchmarks, setting up an automated keyword pipeline can cut a 10-hour manual research project down to just 13 minutes for 1,500 keywords.

A modern pipeline connects data endpoints like the DataForSEO API directly to automation platforms and language models. This hybrid setup tags search intent and runs competitor research while you focus on finding low-hanging fruit keywords to capture fast rankings. The system handles raw data sorting so you can focus on high-level content strategy.
TL;DR: Automate keyword research by combining programmatic API data ingestion from DataForSEO with AI intent classification via Make or Google Gemini. This cuts manual workflow time from hours to minutes, transforming raw seed terms into structured content calendars ready for publishing.
Building a programmatic data pipeline with Make and APIs
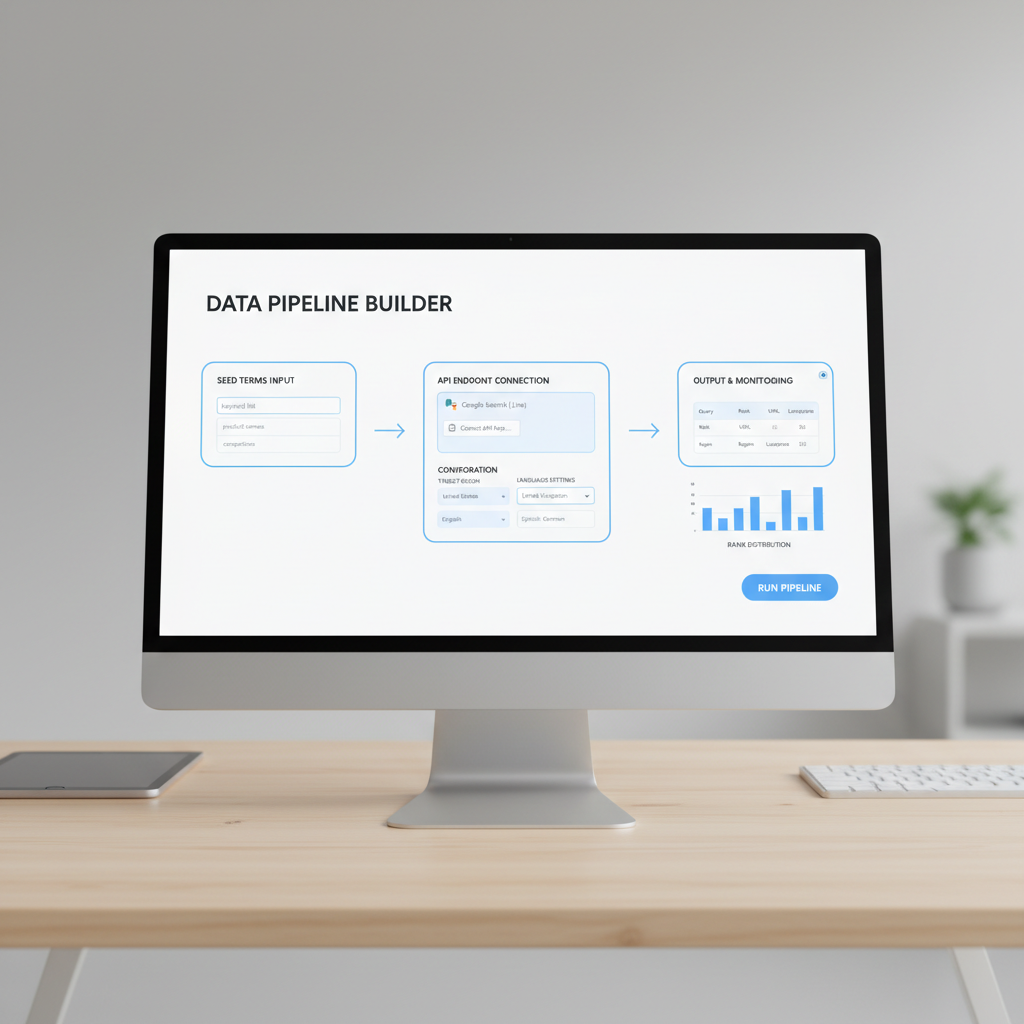
An automated pipeline turns a small list of seed terms into thousands of clean search queries. By connecting Make to the DataForSEO API, you replace manual file downloads with a scheduled data feed. This pulls live metrics straight from Google without fragile browser scraping.
The workflow follows four stages: intake, API querying, rate control, and data filtering.
flowchart LR
    A[Seed Terms in Sheets] --> B[Make Scenario Trigger]
    B --> C[DataForSEO API Request]
    C --> D[Rate Limiter & Queue]
    D --> E[Regex & Volume Filters]
    E --> F[Clean Master Database]
Connecting seed terms to live SERP endpoints
Your pipeline begins with a trigger module. Inside Make, create a scenario that monitors a database. You can watch a Google Sheet for new root topics or trigger on a webhook from an Airtable base.
When you add a seed term, the trigger sends an HTTP request to DataForSEO. Your scenario passes the seed phrase to the keyword suggestions endpoint. The API then returns related phrases, search volume, parent topics, and question variants.
The API sends back a JSON payload with candidate queries and metrics. Parse this JSON payload with a built-in aggregator module. This allows downstream steps to read metrics like cost per click (CPC) and search volume without workflow errors.
Configuring target regions and language settings
Query metrics are misleading if you mix regional data. Set explicit location and language parameters in your API request body instead of using default values.
If you target US buyers, send the country code 2840 and set the language parameter to en. You can also target specific metro codes or coordinates for local intent.
Setting these parameters at the payload level ensures your search volume matches real user queries in your target region.
Managing API rate limiting protocols
Sending hundreds of requests at the same time can trigger rate limits. Managing your request frequency keeps the automation running without 429 Too Many Requests errors.
You can keep your pipeline stable with three simple rules:
- Batch payloads: Group your seeds into batches of 100 queries per call instead of sending single requests.
- Sleep modules: Add a sleep utility to space out heavy request runs.
- Error handlers: Attach a break directive to your HTTP module. If the endpoint returns a rate-limit error, the scenario pauses and retries automatically.
Pruning noise with regex filtering and volume thresholds
Raw keyword data contains brand names you cannot target and rival products you do not sell. You should filter this data before saving it to your primary database.
Use a router module with regular expressions to filter incoming phrases. For example, an email software company can set a negative regex filter like (?i)(mailchimp|constant contact|activecampaign) to remove competitor brand terms. Regex can also separate transactional terms like “buy” or “pricing” from informational queries.
Next, set minimum search volume thresholds. Filter out broad terms with zero monthly queries, and send promising low-competition phrases directly to your production queue.
Automating search intent classification and clustering
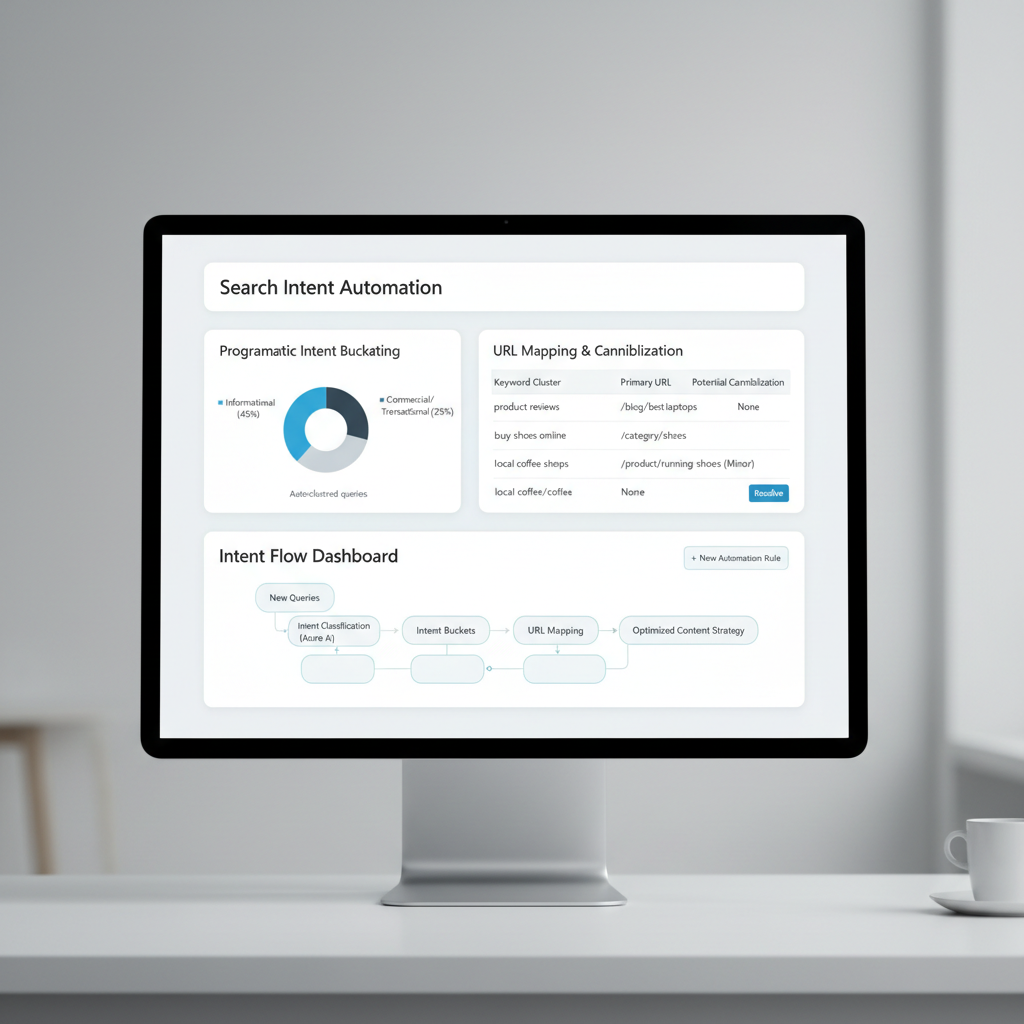
Automating intent classification means using an LLM to categorize user goals before you start writing. Sifting through thousands of queries by hand takes hours. Passing your raw list to a language model like Google Gemini groups keywords into actionable clusters quickly.
Programmatic intent bucketing
Send your keyword lists through an AI prompt with a strict JSON output schema. The prompt should categorize each query into one of three buckets: informational, commercial, or transactional.
A query like “how to set up schema markup” is informational. A search for “best schema markup tools” fits commercial investigation. A search for “buy schema tool subscription” is transactional. Language models understand context and nuance better than simple keyword modifier lists.
URL mapping and preventing cannibalization
Clustering only works if you map each cluster to a specific URL. Without clear mapping, multiple pages will target the same search query and compete against each other.
Assign each keyword cluster to one canonical URL path:
- Informational clusters: Route to top-of-funnel educational articles in your blog directory.
- Commercial clusters: Route to comparison hubs and buyer guides.
- Transactional clusters: Route directly to pricing or product pages.
Every search query should point to one clear destination on your site. You can review our guide on keyword cannibalization fixes to keep your site architecture clean.
Dynamic SERP feature extraction
Intent tags tell you what a searcher wants, while live SERP data shows how to present the answer. Setting up SERP feature extraction helps your system identify what Google displays for each topic.
If a search result features a video carousel or a People Also Ask box, a plain text article might underperform. If the top results are interactive tools, a standard blog post will not rank well. Your workflow should check whether the query requires a step-by-step tutorial, a product grid, a comparison table, or a calculator.
Extracting competitor data using web parsers and spreadsheets
You do not need costly tools to find keyword opportunities on competitor sites. Lightweight scrapers and basic spreadsheet formulas can reveal page structure and content gaps quickly.
Scraping competitor content with no-code tools
Select the top three ranking URLs for your target query. Instead of reading every line manually, use a browser parser or a tool like Zapier to pull text in bulk. You can set a workflow to scrape HTML and send the text into a spreadsheet whenever a competitor publishes a page.
Focus your scraper on structure:
- Title tags and meta descriptions: Reveal how competitors position their content in search snippets.
- H1, H2, and H3 subheadings: Show the topical structure competitors use to answer the query.
- Internal link anchor text: Highlights the related topics competitors prioritize.
- Lists and FAQ sections: Captures concise answers built for featured snippets.
Organizing headings in spreadsheets
Paste your scraped headings into a spreadsheet with separate columns for each competitor URL. Clean up the text by converting it to lowercase and removing extra spaces with this formula:
=LOWER(TRIM(A2))
This makes it easy to compare headings side by side. You can quickly see which core topics appear on every ranking page and spot niche angles that only one competitor covers.
Spotting keyword gaps with formulas and conditional formatting
Use conditional formatting in Google Sheets to highlight overlapping terms across columns. To find structural gaps, use a COUNTIF formula in a nearby column to check how often a term appears:
=COUNTIF(A$2:C$50, "*"&E2&"*")
If all three competitors use a term, your content should address that subtopic too. If only the top-ranking page covers it, you have found a topic gap you can exploit.
Handling regional search data
Scraping works well for national terms, but local searches require extra care. Search engines adjust local results based on where the request comes from. A search for a service from Chicago shows different results than the same search from Phoenix.
To collect accurate local data without skewed results:
- Browser location emulation: Set Chrome DevTools geolocation coordinates to your target city before running your scraper.
- UULE parameters: Add encoded city parameters to the Google search URL to return local rankings for a specific zip code.
- Local keyword filters: Use spreadsheet formulas to separate neighborhood names and city terms from general phrases.
Scaling content creation with all-in-one SEO platforms
Building a custom keyword pipeline with scripts and webhooks offers full flexibility. However, external API changes and broken parsers require ongoing maintenance. Maintaining custom scripts often pulls content teams away from actual publishing.
All-in-one SEO platforms solve this problem by managing discovery, brief creation, and drafting in a single system. You can explore automated content generation tools to handle research and publishing under one roof.
The maintenance free LSI keyword finder | Seobase covers this in more depth.
Streamlining your SEO workflow for better organic visibility
Automating keyword research saves hours of manual work. A single automated workflow can gather search volume, related phrases, and search intent.
Start with a clear root topic, such as a core service or product category. Your workflow can collect related terms, group similar phrases, and flag user intent. For instance, searches around athletic footwear split into purchase queries, brand comparisons, and maintenance questions. These different intents should lead to separate pages.
Review the output before publishing. Automation uncovers patterns, but human review confirms whether a term matches your offer. Compare suggested queries against live search results and remove terms that attract the wrong audience.
Focus on Google entities rather than standalone keywords. Google search documentation and leaked engineering materials confirm that search engines prioritize recognized entities, such as brands, products, places, and concepts. A page about project management software should cover features, integrations, pricing models, and specific use cases, rather than repeating the same keyword in every section.
Broad coverage gives your page more ways to match relevant queries. If the top search results mention templates, reporting, and team permissions, include those subtopics in your outline.
Use a free keyword density analyzer as a quick page check, not as your main ranking strategy. Keyword placement checks can spot awkward phrasing, but helpful detail and matching user intent drive organic performance.
Picking the right workflow for your team
Choose a custom API pipeline if your team needs full control over data feeds and custom databases. This approach works best for teams with developer support who can maintain endpoints and manage error handling.
Choose an all-in-one SEO platform if you want to move directly from keyword discovery to content creation without writing code. These platforms combine keyword research, content briefs, and rank tracking in one workspace.
Start with an all-in-one platform to test your content strategy. Build custom API pipelines only when unique reporting requirements or manual bottlenecks justify the extra development effort.
Pick one priority page, run an automated keyword review, group the queries by intent, and update your content around the main topic gaps.
Frequently asked questions
How can I automate keyword research using AI?
You can automate keyword research by connecting SEO data provider APIs like DataForSEO to Make or Zapier. You then pass the extracted keyword lists through language models like Google Gemini to classify search intent and cluster terms automatically.
What is the best API for automated keyword research?
The DataForSEO Labs API is a reliable option because it provides endpoints for keyword ideas, search volume, CPC, and competitor metrics on a pay-as-you-go model without enterprise lock-ins.
How do I use Make and DataForSEO for keyword automation?
Create a scenario in Make that triggers on a schedule or webhook. The scenario sends your seed terms to the DataForSEO API, filters the returned data, and writes the clean keyword list into Google Sheets or Airtable.
Can I use Zapier to scrape competitor keywords?
Yes. You can use Zapier with web parsers to pull headings and text from competitor URLs, paste the content into a spreadsheet, and run formulas to identify keyword gaps.
How do I group keywords by search intent automatically?
Pass your keyword list to a language model with a prompt that sorts terms into transactional, informational, commercial, or navigational buckets based on semantic meaning.
What tools do I need to automate keyword research?
You need an automation platform like Make or Zapier, an SEO data feed like DataForSEO, and a storage tool like Google Sheets or an all-in-one platform like Seobase.
Is automated keyword research accurate?
Automated keyword research uses data from standard search APIs. It delivers accuracy comparable to major SEO tools while eliminating manual data entry mistakes.
How do I filter out irrelevant keywords automatically?
You can filter irrelevant keywords by applying regular expressions, negative keyword exclusion lists, and minimum search volume thresholds inside your API request or spreadsheet workflow.
Put this on autopilot
Seobase runs the whole loop for you: it finds the keywords worth ranking for, writes and publishes the articles, and reports back from Search Console on what actually moved.
Start a free Seobase workflowIn this guide
- Building a programmatic data pipeline with Make and APIs
- Automating search intent classification and clustering
- Extracting competitor data using web parsers and spreadsheets
- Scaling content creation with all-in-one SEO platforms
- Streamlining your SEO workflow for better organic visibility
- Frequently asked questions